Reference: Section 5.2 in Biegler (2010)
Newton on the equality KKT equations
For C maps , on open , consider subject to , use , row Jacobian , and residual . Its Jacobian is
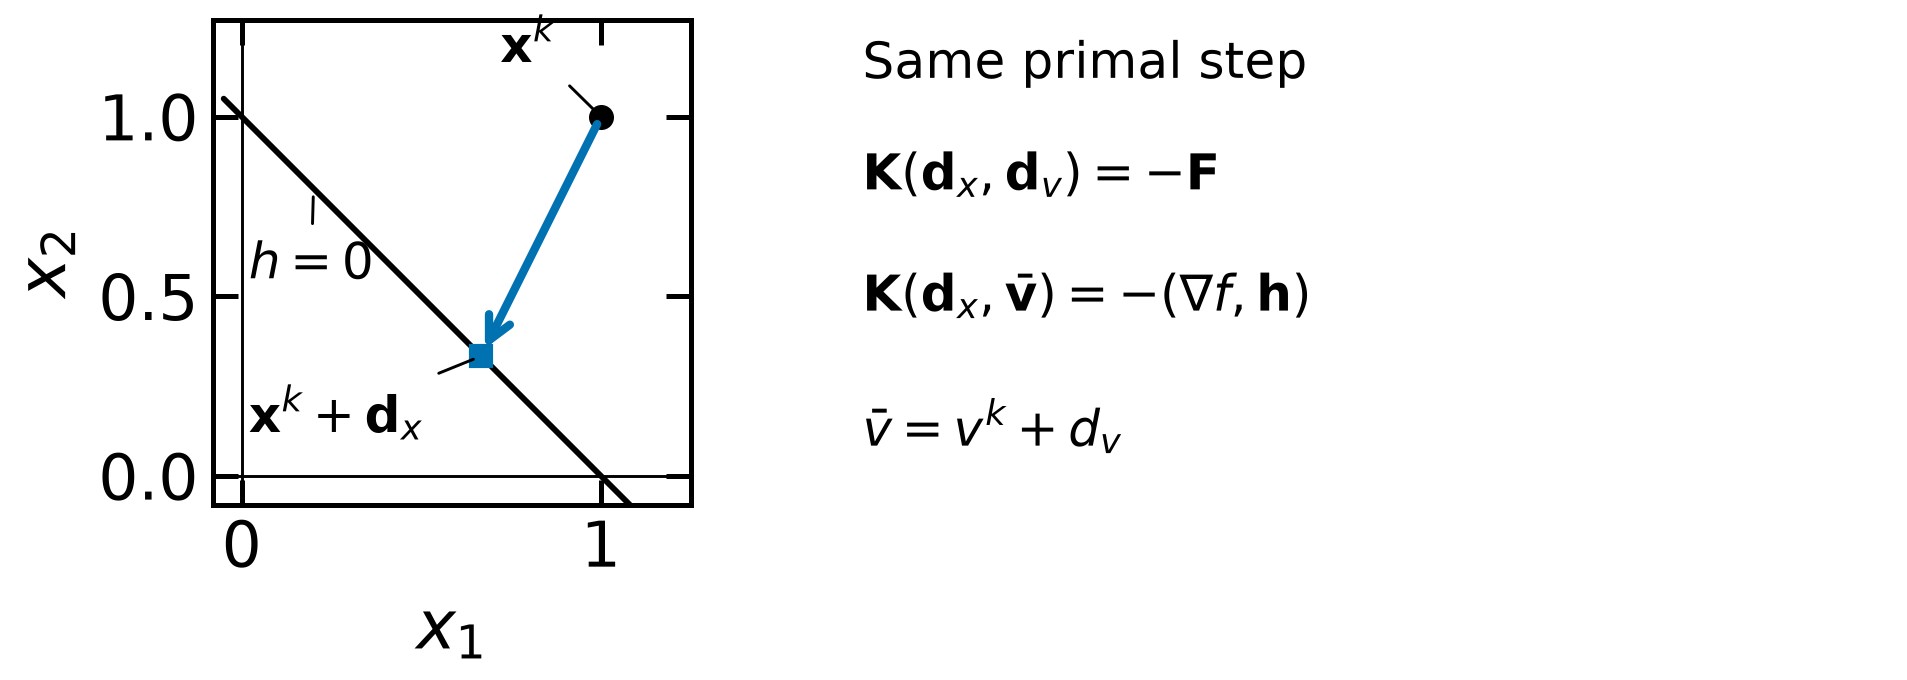
The Newton step solves and updates both variables. Equivalently, set and solve
These are the stationarity equations of subject to . With full-row-rank and , they give the unique constrained-QP minimum even when is indefinite in full space. Without this curvature condition a Newton root is not automatically a QP minimizer. Biegler (5.4)–(5.6), p. 93; Nocedal–Wright (18.2)–(18.9), pp. 530–532.
The existing teaching code below uses a column gradient matrix A, so \mathbf{J}_h = A.T when comparing formulas. Its finite-difference helpers and intentional singular solves and starts near different stationary points remain unchanged.
Helper Functions
# Load required Python libraries.
import matplotlib.pyplot as plt
import numpy as np
from scipy import linalg


## Check if element of array is NaN
def check_nan(A):
    return np.sum(np.isnan(A))


## Calculate gradient with central finite difference
def my_grad_approx(x, f, eps1, verbose=False):
    """
    Calculate gradient of function f using central difference formula

    Inputs:
        x - point for which to evaluate gradient
        f - function to consider
        eps1 - perturbation size

    Outputs:
        grad - gradient (vector)
    """

    n = len(x)
    grad = np.zeros(n)

    if verbose:
        print("***** my_grad_approx at x = ", x, "*****")

    for i in range(0, n):

        # Create vector of zeros except eps in position i
        e = np.zeros(n)
        e[i] = eps1

        # Finite difference formula
        my_f_plus = f(x + e)
        my_f_minus = f(x - e)

        # Diagnostics
        if verbose:
            print("e[", i, "] = ", e)
            print("f(x + e[", i, "]) = ", my_f_plus)
            print("f(x - e[", i, "]) = ", my_f_minus)

        grad[i] = (my_f_plus - my_f_minus) / (2 * eps1)

    if verbose:
        print("***** Done. ***** \n")

    return grad


def my_jac_approx(x, h, eps1, verbose=False):
    """
    Calculate Jacobian of function h(x) using central difference formula

    Inputs:
        x - point for which to evaluate gradient
        h - vector-valued function to consider. h(x): R^n --> R^m
        eps1 - perturbation size

    Outputs:
        A - Jacobian (n x m matrix)
    """

    # Check h(x) at x
    h_x0 = h(x)

    # Extract dimensions
    n = len(x)
    m = len(h_x0)

    # Initialize Jacobian matrix
    A = np.zeros((n, m))

    # Calculate Jacobian by row
    for i in range(0, n):

        # Create vector of zeros except eps in position i
        e = np.zeros(n)
        e[i] = eps1

        # Finite difference formula
        my_h_plus = h(x + e)
        my_h_minus = h(x - e)

        # Diagnostics
        if verbose:
            print("e[", i, "] = ", e)
            print("h(x + e[", i, "]) = ", my_h_plus)
            print("h(x - e[", i, "]) = ", my_h_minus)

        A[i, :] = (my_h_plus - my_h_minus) / (2 * eps1)

    if verbose:
        print("***** Done. ***** \n")

    return A


## Calculate gradient using central finite difference and my_hes_approx
def my_hes_approx(x, grad, eps2):
    """
    Calculate gradient of function my_f using central difference formula and my_grad

    Inputs:
        x - point for which to evaluate gradient
        grad - function to calculate the gradient
        eps2 - perturbation size (for Hessian NOT gradient approximation)

    Outputs:
        H - Hessian (matrix)
    """

    n = len(x)
    H = np.zeros([n, n])

    for i in range(0, n):
        # Create vector of zeros except eps in position i
        e = np.zeros(n)
        e[i] = eps2

        # Evaluate gradient twice
        grad_plus = grad(x + e)
        grad_minus = grad(x - e)

        # Notice we are building the Hessian by column (or row)
        H[:, i] = (grad_plus - grad_minus) / (2 * eps2)

    return H


## Linear algebra calculation
def xxT(u):
    """
    Calculates u*u.T to circumvent limitation with SciPy

    Arguments:
    u - numpy 1D array

    Returns:
    u*u.T

    Assume u is a nx1 vector.
    Recall: NumPy does not distinguish between row or column vectors

    u.dot(u) returns a scalar. This function returns an nxn matrix.
    """

    n = len(u)
    A = np.zeros([n, n])
    for i in range(0, n):
        for j in range(0, n):
            A[i, j] = u[i] * u[j]

    return A


## Analyze Hessian
def analyze_hes(B):
    print(B, "\n")

    l = linalg.eigvals(B)
    print("Eigenvalues: ", l, "\n")
Algorithm 5.1
def alg51(x0, calc_f, calc_h, eps1=1e-6, eps2=1e-6, max_iter=50, verbose=False):
    """
    Basic Full Space Newton Method for Equality Constrained NLP

    Input:
        x0 - starting point (vector)
        calc_f - function to calculate objective (returns scalar)
        calc_h - function to calculate constraints (returns vector)
        eps1 - tolerance for primal and dual steps
        eps2 - tolerance for gradient of L1

    Outputs:
        x - history of steps (primal variables)
        v - history of steps (dual variables)
        f - history of objective evaluations
        h - history of constraint evaluations
        df - history of objective gradients
        dL - history of Lagrange function gradients
        A - history of constraint Jacobians
        W - history of Lagrange Hessians

    Notes:
        1. For simplicity, central finite difference is used
           for all gradient calculations.
    """

    # Declare iteration histories as empty lists
    x = []
    v = []
    f = []
    L = []
    h = []
    df = []
    dL = []
    A = []
    W = []

    # Flag for iterations
    flag = True

    # Iteration counter
    k = 0

    # Copy initial point to primal variable history
    n = len(x0)
    x.append(x0)

    # Evaluate objective and constraints at initial point
    f.append(calc_f(x0))
    h.append(calc_h(x0))

    # Determine number of equality constraints
    m = len(h[0])

    # Initial dual variables with vector of ones
    v.append(np.ones(m))

    # Print header for iteration information
    print("Iter. \tf(x) \t\t||h(x)|| \t||grad_L(x)|| \t||dx|| \t\t||dv||")

    while flag and k < max_iter:

        # STEP 1. Construct KKT matrix

        if k > 0:
            # Evaluate objective function
            f.append(calc_f(x[k]))

            # Evaluate constraint function
            h.append(calc_h(x[k]))

        # Evaluate objective gradient
        df.append(my_grad_approx(x[k], calc_f, 1e-6))

        # Evaluate constraint Jacobian
        A.append(my_jac_approx(x[k], calc_h, 1e-6))

        # Evaluate gradient of Lagrange function
        L_func = lambda x_: calc_f(x_) + (calc_h(x_)).dot(v[k])
        L_grad = lambda x_: my_grad_approx(x_, L_func, 1e-6)
        dL.append(L_grad(x[k]))
        norm_dL = linalg.norm(dL[k])

        # Evaluate Hessian of Lagrange function
        W.append(my_hes_approx(x[k], L_grad, 1e-6))

        if verbose:
            print("*** k =", k, " ***")
            print("x_k =", x[k])
            print("v_k =", v[k])
            print("f_k =", f[k])
            print("df_k =", df[k])
            print("h_k =", h[k])
            print("A_k =\n", A[k])
            print("W_k =\n", W[k])
            print("\n")

        # Assemble KKT matrix
        KKT_top = np.concatenate((W[k], A[k]), axis=1)
        KKT_bot = np.concatenate((A[k].T, np.zeros((m, m))), axis=1)
        KKT = np.concatenate((KKT_top, KKT_bot), axis=0)

        if verbose:
            print("KKT matrix =\n", KKT, "\n")

        # Check if KKT matrix is singular
        l, eigvec = linalg.eig(KKT)

        if verbose:
            print("KKT matrix eigenvalues:")
            print(l)

        zero_eigenvalues = sum(np.abs(l) <= 1e-8)

        if zero_eigenvalues > 0:
            flag = False
            print("KKT matrix is singular. Eigenvalues:\n")
            print(l, "\n")

        ## STEP 2. Solve linear system.

        if flag:
            b = -np.concatenate((dL[k], h[k]), axis=0)
            z = linalg.solve(KKT, b)
        else:
            z = []

        ## STEP 3. Take step
        if flag:
            dx = z[0:n]
            dv = z[n : n + m]

            x.append(x[k] + dx)
            v.append(v[k] + dv)

            norm_dx = linalg.norm(dx)
            norm_dv = linalg.norm(dv)

        ## Print iteration information
        print(
            k,
            "  \t{0: 1.4e} \t{1:1.4e} \t{2:1.4e}".format(
                f[k], linalg.norm(h[k]), norm_dL
            ),
            end="",
        )

        if flag:
            print(" \t{0: 1.4e} \t{1: 1.4e}".format(norm_dx, norm_dv), end="\n")
        else:
            print(" \t -------  \t -------", end="\n")

        # Increment counter
        k = k + 1

        ## Check convergence criteria
        if flag:
            flag = norm_dx > eps1 and norm_dv > eps1 and norm_dL > eps2

    if flag and k >= max_iter:
        print("Reached maximum number of iterations.")

return x, v, f, h, df, dL, A, Wdef my_f(x):
return x[0] ** 2 + 2 * x[1] ** 2 - 1 * x[2]
def my_h(x):
h = np.zeros(2)
h[0] = x[0] + x[1] - 1
h[1] = x[0] + x[1] - x[2] - 5
return hTest Finite Difference Approximations
## Define initial point
x0 = np.array([1, 1, 1])

## Calculate objective
print("f(x0) =", my_f(x0), "\n")

## Calculate constraints
print("h(x0) =", my_h(x0), "\n")

## Calculate objective gradient
print("df(x0) =", my_grad_approx(x0, my_f, 1e-6), "\n")

## Calculate constraint Jacobian
print("dh(x0) =\n", my_jac_approx(x0, my_h, 1e-6), "\n")
f(x0) = 2
h(x0) = [ 1. -4.]
df(x0) = [ 2. 4. -1.]
dh(x0) =
[[ 1. 1.]
[ 1. 1.]
[ 0. -1.]]
Test Algorithm 5.1
## Run Algorithm 5.1 on test problem
results = alg51(x0, my_f, my_h)

## Display results
xstar = results[0][-1]
print("\nx* =", xstar)

## Display results
vstar = results[1][-1]
print("\nv* =", vstar)
Iter. f(x) ||h(x)|| ||grad_L(x)|| ||dx|| ||dv||
0 2.0000e+00 4.1231e+00 7.4833e+00 5.0553e+00 2.4040e+00
1 4.6667e+00 5.7632e-10 8.2956e-04 1.4999e-04 6.2902e-04
2 4.6667e+00 1.7764e-14 2.3453e-08 7.7457e-09 7.2674e-09
x* = [ 0.66666667 0.33333333 -4. ]
v* = [-0.33333333 -1. ]
# Analytic checks at the last appended point; original algorithm is unchanged.
xr = np.asarray(results[0][-1], dtype=float)
vr = np.asarray(results[1][-1], dtype=float)
gf = np.array([2*xr[0],4*xr[1],-1.0])
Jr = np.array([[1,1,0],[1,1,-1]])
hr = np.array([xr[0]+xr[1]-1,xr[0]+xr[1]-xr[2]-5])
print("Last-point feasibility infinity norm:", np.linalg.norm(hr, np.inf))
print("Last-point stationarity infinity norm:", np.linalg.norm(gf+Jr.T@vr, np.inf))
Last-point feasibility infinity norm: 2.220446049250313e-16
Last-point stationarity infinity norm: 2.513835806183806e-10
Example Problem 2
Can we break Algorithm 5.1?
Probably. Let us try a model where is always rank-deficient.
Consider:
Test Algorithm 5.1 with the redundant constraint
def my_f2(x):
    return x[0] ** 2 + 2 * x[1] ** 2


def my_h2(x):
    h = np.zeros(2)
    h[0] = x[0] + x[1] - 1
    h[1] = h[0]
    return h


x0 = np.array((1, 1))

## Run Algorithm 5.1 on test problem
results = alg51(x0, my_f2, my_h2)

## Display results
xstar = results[0][-1]
print("\nx* =", xstar)

## Display results
vstar = results[1][-1]
print("\nv* =", vstar)
Iter. f(x) ||h(x)|| ||grad_L(x)|| ||dx|| ||dv||
KKT matrix is singular. Eigenvalues:
[ 4.53361158e+00+0.j 2.51704031e+00+0.j -1.05145076e+00+0.j
4.89022718e-33+0.j]
0 3.0000e+00 1.4142e+00 7.2111e+00 ------- -------
x* = [1 1]
v* = [1. 1.]
# Analytic checks at the last appended point; original algorithm is unchanged.
xr = np.asarray(results[0][-1], dtype=float)
vr = np.asarray(results[1][-1], dtype=float)
gf = np.array([2*xr[0],4*xr[1]])
Jr = np.ones((2,2))
hr = np.repeat(xr.sum()-1,2)
print("Last-point feasibility infinity norm:", np.linalg.norm(hr, np.inf))
print("Last-point stationarity infinity norm:", np.linalg.norm(gf+Jr.T@vr, np.inf))
Last-point feasibility infinity norm: 1.0
Last-point stationarity infinity norm: 6.0
Trying Algorithm 5.1 again without the redundant constraint
def my_h2b(x):
    return (x[0] + x[1] - 1) * np.ones(1)


x0 = np.array((1, 1))

## Run Algorithm 5.1 on test problem
results = alg51(x0, my_f2, my_h2b)

## Display results
xstar = results[0][-1]
print("\nx* =", xstar)

## Display results
vstar = results[1][-1]
print("\nv* =", vstar)
Iter. f(x) ||h(x)|| ||grad_L(x)|| ||dx|| ||dv||
0 3.0000e+00 1.0000e+00 5.8310e+00 7.4537e-01 2.3335e+00
1 6.6667e-01 1.3978e-10 2.9473e-04 4.5325e-05 1.5285e-04
2 6.6667e-01 1.7764e-15 2.8419e-09 7.9814e-10 5.1808e-10
x* = [0.66666667 0.33333333]
v* = [-1.33333333]
# Analytic checks at the last appended point; original algorithm is unchanged.
xr = np.asarray(results[0][-1], dtype=float)
vr = np.asarray(results[1][-1], dtype=float)
gf = np.array([2*xr[0],4*xr[1]])
Jr = np.ones((1,2))
hr = np.repeat(xr.sum()-1,1)
print("Last-point feasibility infinity norm:", np.linalg.norm(hr, np.inf))
print("Last-point stationarity infinity norm:", np.linalg.norm(gf+Jr.T@vr, np.inf))
Last-point feasibility infinity norm: 0.0
Last-point stationarity infinity norm: 4.312461499011988e-11
Example Problem 3
Can we break Algorithm 5.1 in another way?
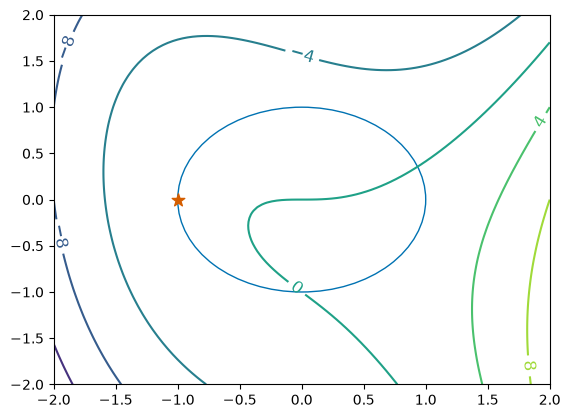
Let us try a model where is full rank but there are multiple local optima.
Consider:
def my_f3(x):
    return x[0] ** 3 - x[1] - x[0] * x[1] - x[1] ** 2


def my_h3(x):
return (x[0] ** 2 + x[1] ** 2 - 1) * np.ones(1)Visualize
def visualize(xk=[]):
    n1 = 101
    n2 = 101
    x1eval = np.linspace(-2, 2, n1)
    x2eval = np.linspace(-2, 2, n2)

    X, Y = np.meshgrid(x1eval, x2eval)

    Z = np.zeros([n2, n1])

    for i in range(0, n1):
        for j in range(0, n2):
            Z[j, i] = my_f3((X[j, i], Y[j, i]))

    fig, ax = plt.subplots(1, 1)
    CS = ax.contour(X, Y, Z)
    ax.clabel(CS, inline=1, fontsize=12)

    # Add unit circle
    # Okabe-Ito blue (figures/dowling.mplstyle), was matplotlib's "b".
    circ = plt.Circle((0, 0), radius=1, edgecolor="#0072B2", facecolor="None")
    ax.add_patch(circ)

    # Plot iteration history
    if len(xk) > 0:
        for i in range(0, len(xk)):
            if i == len(xk) - 1:
                c = "#D55E00"  # Okabe-Ito vermillion: the final iterate
            else:
                c = "black"
            plt.scatter(
                (xk[i][0]),
                (xk[i][1]),
                marker="*" if i == len(xk) - 1 else "o",
                s=90 if i == len(xk) - 1 else 30,
                color=c,
            )

    plt.xlim([-2, 2])
    plt.ylim([-2, 2])


visualize()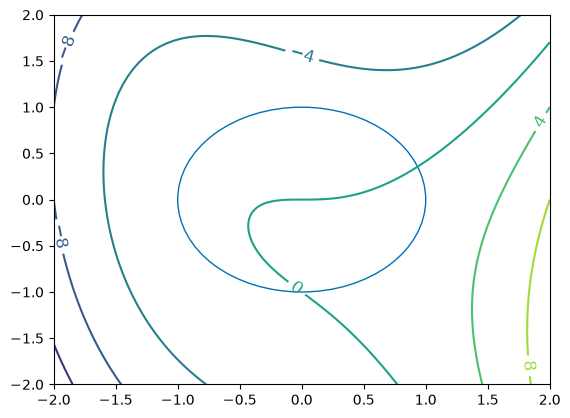
nt = 200
theta = np.linspace(0, 2 * np.pi, nt)
obj = np.zeros(nt)


for i in range(0, nt):
    x_ = np.cos(theta[i])
    y_ = np.sin(theta[i])

    obj[i] = my_f3((x_, y_))


plt.figure()
plt.plot(theta, obj)
plt.xlabel("$\\theta$ [radians]")
plt.ylabel("Objective")
plt.grid()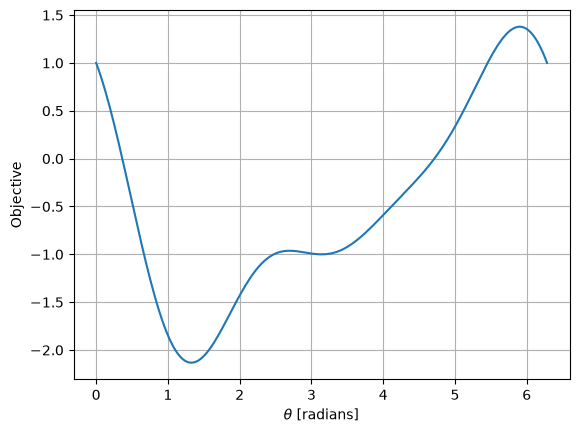
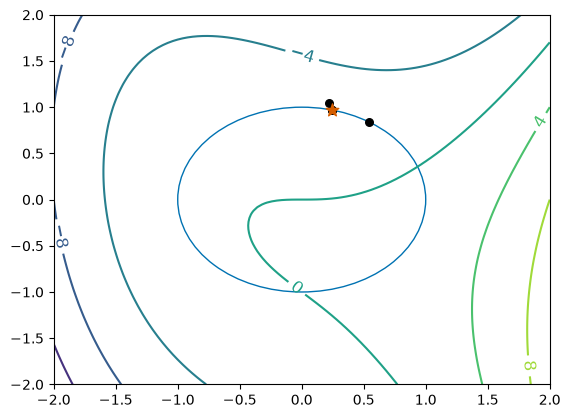
Starting Point Near Global Min ()
theta0 = 1.0
x0 = np.array((np.cos(theta0), np.sin(theta0)))

## Run Algorithm 5.1 on test problem
results = alg51(x0, my_f3, my_h3)

## Display results
xstar = results[0][-1]
print("\nx* =", xstar)

## Display results
vstar = results[1][-1]
print("\nv* =", vstar)

## Convert into theta
print("\ntheta* =", np.arccos(xstar[0]), "=", np.arcsin(xstar[1]))

## Visualize
visualize(results[0])
Iter. f(x) ||h(x)|| ||grad_L(x)|| ||dx|| ||dv||
0 -1.8465e+00 0.0000e+00 1.9015e+00 3.8312e-01 7.2367e-01
1 -2.3659e+00 1.4678e-01 3.3718e-01 7.8768e-02 7.9620e-02
2 -2.1425e+00 6.2044e-03 1.2116e-02 3.2309e-03 3.9114e-03
3 -2.1324e+00 1.0439e-05 2.4821e-05 5.3713e-06 9.2590e-06
4 -2.1323e+00 2.8850e-11 6.2804e-10 6.6450e-11 2.6422e-10
x* = [0.24215301 0.97023807]
v* = [1.64012794]
theta* = 1.3262120357381408 = 1.3262120357381406
# Analytic checks at the last appended point; original algorithm is unchanged.
xr = np.asarray(results[0][-1], dtype=float)
vr = np.asarray(results[1][-1], dtype=float)
gf = np.array([3*xr[0]**2-xr[1], -1-xr[0]-2*xr[1]])
Jr = np.array([2*xr]); hr = np.array([xr@xr-1])
Wr = np.array([[6*xr[0],-1.0],[-1.0,-2.0]]) + 2*vr[0]*np.eye(2)
Zr = np.array([-xr[1],xr[0]])/np.linalg.norm(xr)
print("Final tangent curvature:", Zr@Wr@Zr)
print("Angle from atan2:", np.arctan2(xr[1],xr[0]) % (2*np.pi))
print("Last-point feasibility infinity norm:", np.linalg.norm(hr, np.inf))
print("Last-point stationarity infinity norm:", np.linalg.norm(gf+Jr.T@vr, np.inf))
Final tangent curvature: 5.000593598281122
Angle from atan2: 1.3262120357381408
Last-point feasibility infinity norm: 1.1102230246251565e-16
Last-point stationarity infinity norm: 2.501550078193304e-10
Starting Point Near Local Min ()
theta0 = np.pi
x0 = np.array((np.cos(theta0), np.sin(theta0)))

## Run Algorithm 5.1 on test problem
results = alg51(x0, my_f3, my_h3)

## Display results
xstar = results[0][-1]
print("\nx* =", xstar)

## Display results
vstar = results[1][-1]
print("\nv* =", vstar)

## Convert into theta
print("\ntheta* =", np.arccos(xstar[0]), "(using arccos)")
print("\ntheta* =", np.arcsin(xstar[1]), "(using arcsin)")

## Visualize
visualize(results[0])
Iter. f(x) ||h(x)|| ||grad_L(x)|| ||dx|| ||dv||
KKT matrix is singular. Eigenvalues:
[-4.9999744 +0.j 1.00000737+0.j 0. +0.j]
0 -1.0000e+00 0.0000e+00 1.0000e+00 ------- -------
x* = [-1.0000000e+00 1.2246468e-16]
v* = [1.]
theta* = 3.141592653589793 (using arccos)
theta* = 1.2246467991473532e-16 (using arcsin)
# Analytic checks at the last appended point; original algorithm is unchanged.
xr = np.asarray(results[0][-1], dtype=float)
vr = np.asarray(results[1][-1], dtype=float)
gf = np.array([3*xr[0]**2-xr[1], -1-xr[0]-2*xr[1]])
Jr = np.array([2*xr]); hr = np.array([xr@xr-1])
Wr = np.array([[6*xr[0],-1.0],[-1.0,-2.0]]) + 2*vr[0]*np.eye(2)
Zr = np.array([-xr[1],xr[0]])/np.linalg.norm(xr)
print("Final tangent curvature:", Zr@Wr@Zr)
print("Angle from atan2:", np.arctan2(xr[1],xr[0]) % (2*np.pi))
print("Last-point feasibility infinity norm:", np.linalg.norm(hr, np.inf))
print("Last-point stationarity infinity norm:", np.linalg.norm(gf+Jr.T@vr, np.inf))
Final tangent curvature: -2.449293598294707e-16
Angle from atan2: 3.141592653589793
Last-point feasibility infinity norm: 0.0
Last-point stationarity infinity norm: 1.0
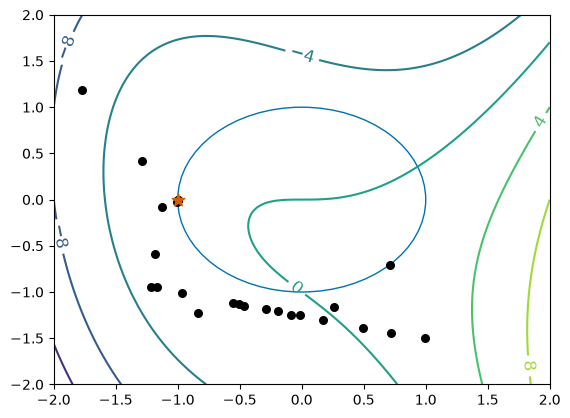
Starting Point Near Global Max ()
theta0 = 5.5
x0 = np.array((np.cos(theta0), np.sin(theta0)))

## Run Algorithm 5.1 on test problem
results = alg51(x0, my_f3, my_h3)

## Display results
xstar = results[0][-1]
print("\nx* =", xstar)

## Display results
vstar = results[1][-1]
print("\nv* =", vstar)

## Convert into theta
print("\ntheta* =", np.arccos(xstar[0]), "(using arccos)")
print("\ntheta* =", np.arcsin(xstar[1]), "(using arcsin)")

## Visualize
visualize(results[0])
Iter. f(x) ||h(x)|| ||grad_L(x)|| ||dx|| ||dv||
0 1.0637e+00 0.0000e+00 4.0116e+00 6.3909e-01 8.9136e-01
1 1.3218e-01 4.0844e-01 1.6281e+00 1.0969e+00 8.7287e-01
2 -1.8894e+00 1.2033e+00 1.6888e+00 7.5228e-01 3.5435e-01
3 -4.1714e-01 5.6592e-01 1.1635e+00 1.1219e+00 3.4964e-01
4 -2.6420e+00 1.2587e+00 2.7574e+00 7.3097e-01 2.5496e-01
5 -8.0250e-01 5.3431e-01 1.1284e+00 1.4981e+00 5.0319e-01
6 1.7124e+00 2.2442e+00 4.9042e+00 8.4722e-01 2.8637e-01
7 -1.6357e-01 7.1778e-01 1.5622e+00 7.4282e-01 2.5260e-01
8 -9.1296e-01 5.5178e-01 1.1957e+00 1.0771e+00 3.6784e-01
9 2.7058e-01 1.1601e+00 2.5066e+00 7.0715e-01 2.4131e-01
10 -4.9283e-01 5.0006e-01 1.0812e+00 2.2231e+00 7.5807e-01
11 -1.4243e+01 4.9420e+00 1.0690e+01 1.1699e+00 3.9830e-01
12 -2.8817e+00 1.3688e+00 2.9630e+00 7.3077e-01 2.5031e-01
13 -8.4751e-01 5.3403e-01 1.1512e+00 1.2604e+00 4.2884e-01
14 7.6837e-01 1.5886e+00 3.4414e+00 7.5685e-01 2.5779e-01
15 -3.3893e-01 5.7282e-01 1.2400e+00 9.7568e-01 3.3264e-01
16 -1.8779e+00 9.5195e-01 2.0593e+00 6.9831e-01 2.3823e-01
17 -5.8175e-01 4.8763e-01 1.0544e+00 1.4982e+01 5.1088e+00
18 -3.2163e+03 2.2447e+02 4.8554e+02 7.4948e+00 2.5899e+00
19 -4.2227e+02 5.6172e+01 1.2172e+02 3.7638e+00 1.2478e+00
20 -5.9476e+01 1.4166e+01 3.0621e+01 1.9121e+00 6.4537e-01
21 -9.6877e+00 3.6561e+00 7.9199e+00 8.6310e-01 1.1198e-01
22 -2.1056e+00 7.4493e-01 1.9962e+00 3.7413e+00 2.2160e+00
23 -2.1187e+01 1.3997e+01 1.5350e+01 1.8815e+00 1.1199e+00
24 -6.0601e+00 3.5399e+00 3.7863e+00 9.0823e-01 5.6880e-01
25 -2.1785e+00 8.2488e-01 8.8496e-01 5.1839e-01 1.7278e-02
26 -1.4345e+00 2.6873e-01 7.5002e-02 1.2758e-01 1.6485e-01
27 -1.0244e+00 1.6277e-02 1.7714e-02 2.4213e-02 2.1577e-02
28 -1.0009e+00 5.8627e-04 1.0047e-03 1.3111e-03 1.1530e-03
29 -1.0000e+00 1.7191e-06 2.9334e-06 3.8623e-06 3.3699e-06
30 -1.0000e+00 1.4918e-11 3.8858e-10 3.9612e-10 2.0920e-10
x* = [-1.00000000e+00 9.33065018e-12]
v* = [1.5]
theta* = 3.141592653589793 (using arccos)
theta* = 9.330650180104111e-12 (using arcsin)
# Analytic checks at the last appended point; original algorithm is unchanged.
xr = np.asarray(results[0][-1], dtype=float)
vr = np.asarray(results[1][-1], dtype=float)
gf = np.array([3*xr[0]**2-xr[1], -1-xr[0]-2*xr[1]])
Jr = np.array([2*xr]); hr = np.array([xr@xr-1])
Wr = np.array([[6*xr[0],-1.0],[-1.0,-2.0]]) + 2*vr[0]*np.eye(2)
Zr = np.array([-xr[1],xr[0]])/np.linalg.norm(xr)
print("Final tangent curvature:", Zr@Wr@Zr)
print("Angle from atan2:", np.arctan2(xr[1],xr[0]) % (2*np.pi))
print("Last-point feasibility infinity norm:", np.linalg.norm(hr, np.inf))
print("Last-point stationarity infinity norm:", np.linalg.norm(gf+Jr.T@vr, np.inf))
Final tangent curvature: 1.0000000000199956
Angle from atan2: 3.141592653580463
Last-point feasibility infinity norm: 0.0
Last-point stationarity infinity norm: 4.7987835927187916e-11
Reference: equality geometry, decomposition, and local convergence
Nonlinear equalities do not automatically imply a nonconvex feasible set. A circle is nonconvex: the chord between two distinct feasible points leaves its boundary. The nonlinear equation defines the affine line and has nonzero gradient there. The structural convex-NLP definition uses affine equalities, while the actual set must be checked from its representation. See the convexity reference for the first-use domain/set proof.
For data, a local equality-constrained minimum satisfying LICQ has ; a feasible KKT point with is a strict local minimum. These are the equality-only specializations of the second-order reference, rather than different theorems to memorize.
Full and reduced steps
Assume has full row rank and the step uses the unregularized equality row . Let have nonsingular, and let span so is nonsingular. Write :
The first equation restores the linearized constraint. Multiplying the stationarity row by eliminates the multiplier, yielding the second equation. Once the full step is known,
This is algebraically equivalent to the full KKT solve when the matrices are nonsingular. Tangential optimization contains the coupling ; it is not an independent minimization that ignores the normal step.
An orthonormal QR choice has , . For one constraint , the minimum-length normal displacement is . A coordinate choice gives when ; its length relative to the orthogonal normal step is , which grows as that basic coefficient approaches zero. The total unregularized Newton step is basis invariant; its decomposition and conditioning are not.
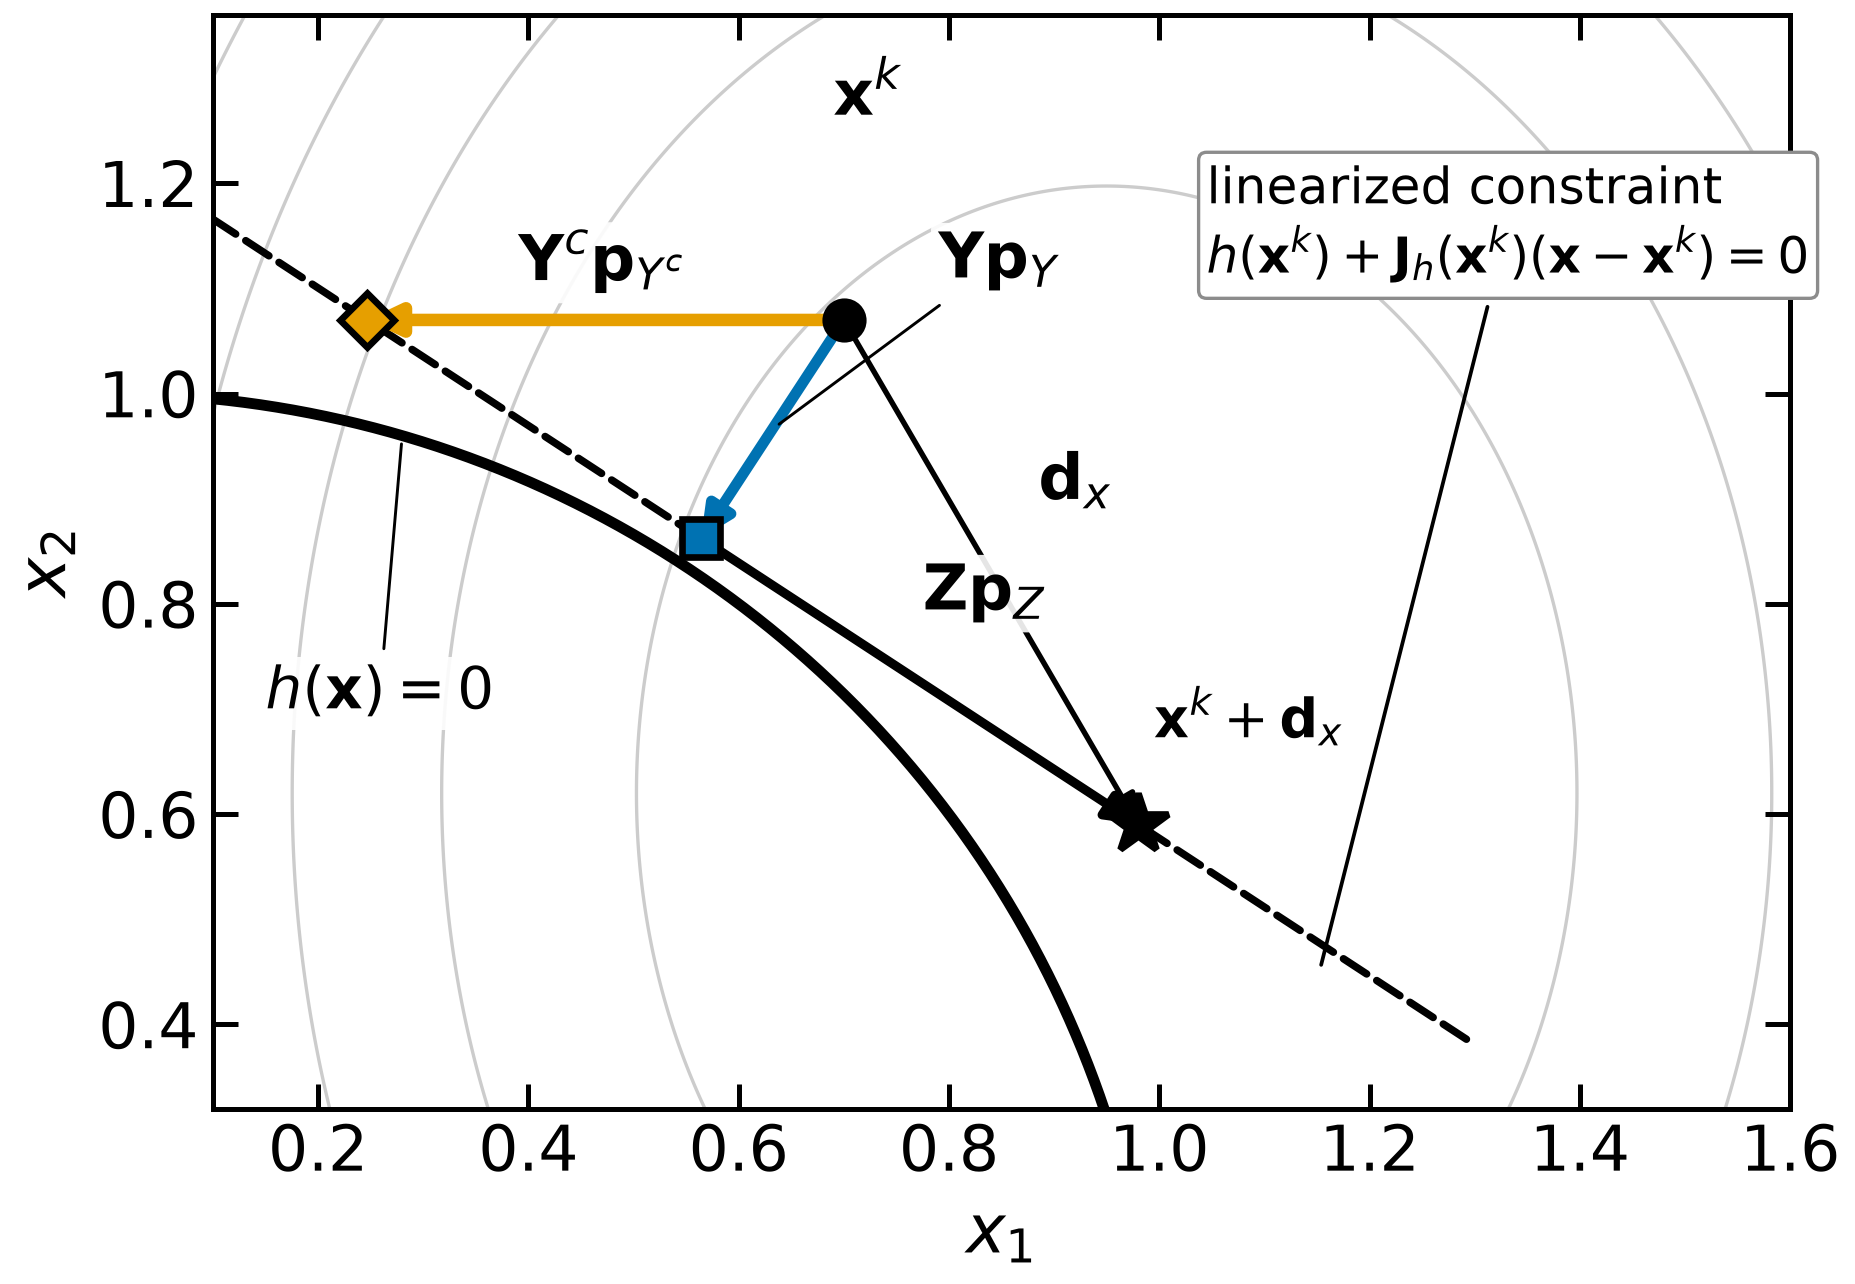
The prepared example has , , and . The orthogonal normal length is 0.2483; the x1-coordinate normal length is 0.4535, ratio 1.8266. Both hit the linearized constraint; neither alone promises exact nonlinear feasibility. Its complete objective is , , . With , choose , , estimate , and form . The displayed tangential equation gives and . These inputs reproduce every displacement in the illustration; it is a distinct toy model, not the nonlinear notebook experiment.
Full-space sparse symmetric factorizations can exploit a sparse KKT matrix. Reduced space is attractive when the effective dimension is small and the basis/projection can be formed or applied efficiently. Dense data alone is not a universal rule. Gould, Hribar and Nocedal (2001), Section 3, pp. 1380–1381, give a projection method that avoids explicitly forming ; Biegler, Sections 5.3.1–5.3.2, pp. 96–102, develops coordinate and orthogonal alternatives.
Coordinate and orthogonal bases without a complete dense QR
Permute the variables so with a nonsingular basic block. Then
Apply through sparse solves with rather than forming its dense inverse. The first-order multiplier estimate drops the step-dependent term from the exact formula above; it is asymptotically consistent when the step tends to zero, but is not algebraically identical away from the solution.
The alternative obeys . Write . Then
One may apply to exchange an -dimensional solve for an -dimensional solve when that is favorable. Neither nor is generally normalized. Biegler, (5.22)–(5.27), p. 101. The minimum-length normal displacement is orthogonal to ; a coordinate normal step can be longer and need not be perpendicular to the tangential component.
Gould et al., (3.3)–(3.8), p. 1380, apply the orthogonal projector without forming a basis:
Their generalized preconditioned system (3.11), p. 1381, replaces by with positive curvature on . The paper also warns that projected residuals can lose relative accuracy through cancellation; avoiding an explicit basis does not remove numerical error. Factorization structure, fill, conditioning, and residual checks govern the implementation choice.
The precise quadratic-convergence promise
Let an equality KKT solution satisfy LICQ and SOSC. If have locally Lipschitz Hessians, and both starting components are sufficiently close, the exact full-step Newton method has for the combined primal/dual error . There exist for which every start within the -ball has well-defined exact steps obeying this bound for all . Merely assuming data does not supply this quadratic rate. Biegler, Theorem 5.1, p. 93; Nocedal–Wright, equality-Newton/QP discussion, pp. 530–532.
Its nonsingular KKT Jacobian follows from full row rank and positive reduced Hessian; the inertia reference proves the signature identity. Apply the existing Newton error proof to : . A bounded inverse and a Lipschitz derivative bound give . This specializes the canonical proof without copying its full integral/norm lesson.
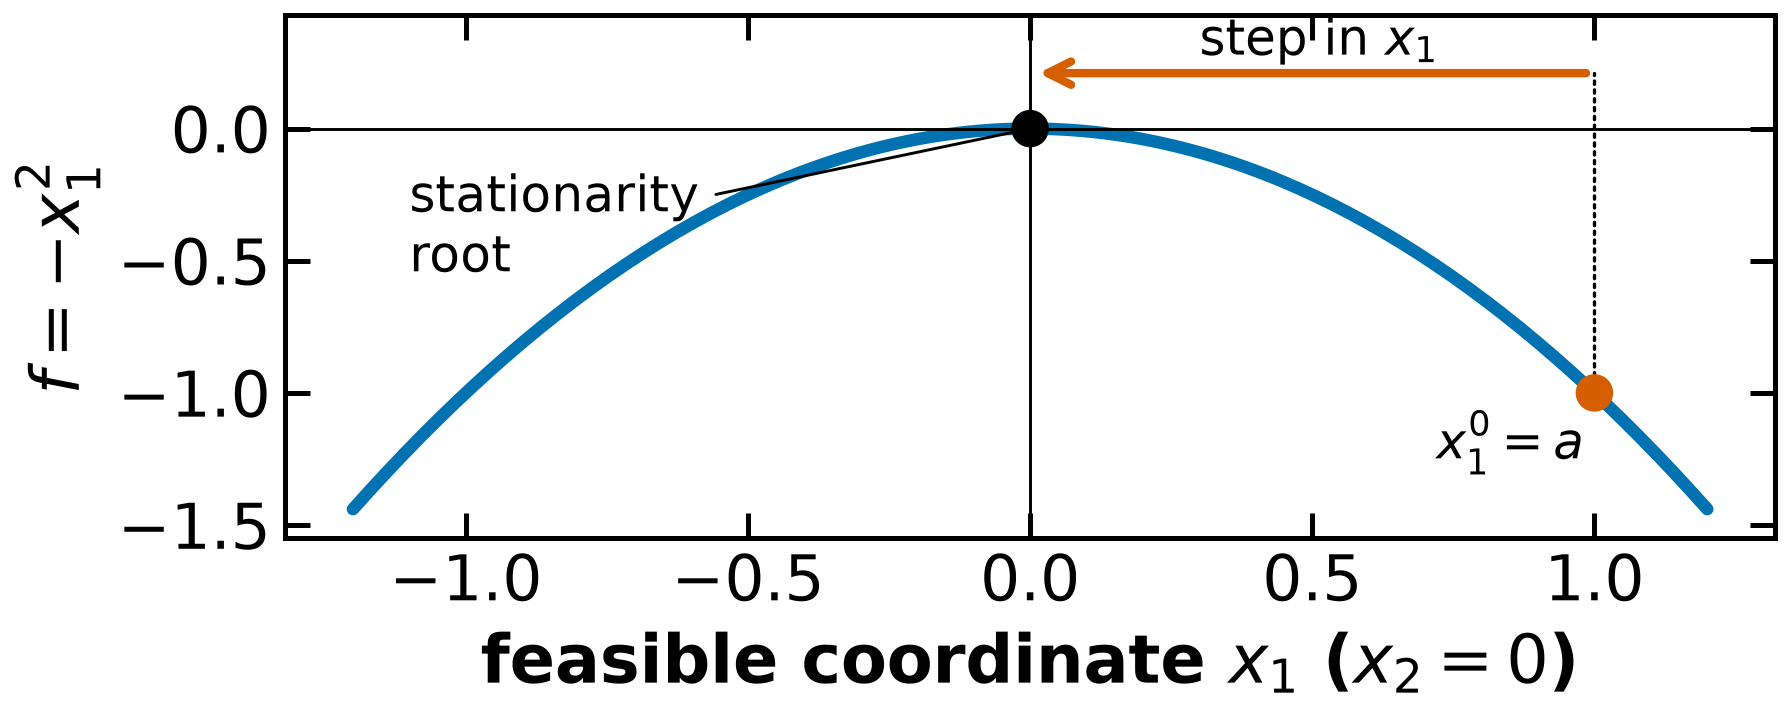
Newton can converge to a maximum or saddle because it seeks a stationarity root. For , , starting at gives and reaches the maximum at zero, raising the objective from to zero.
Read the teaching implementation’s termination carefully
The existing algorithms use finite differences, an iteration cap, and step/gradient stopping logic. They are demonstrations, not production convergence certificates. Their loop can stop when one tested quantity becomes small; it does not require every feasibility/stationarity residual to be small. Re-evaluate and at the last appended point, rather than using an older history entry. A small dual step alone is not optimality, and a finite-difference Newton run is not a proof of the exact-derivative quadratic rate. Keep the singular solves and different starting-point outcomes as intentional experiments. At the circle point the correct multiplier is and the unit-tangent curvature is 1, a local minimum. The original start uses , which makes the initial KKT matrix singular even though the primal point is a minimum. The new analytic residual cells distinguish that failed start from a solved KKT point. Use atan2 to distinguish angle branches; arcsin alone can report an angle near zero for a point near .
Residuals and the textbook stopping correction
An exact Newton iteration evaluates and its Jacobian at the current primal/dual point, solves , then updates both components. Biegler’s Algorithm 5.1, p. 93, errata lines 18–19 adds the feasibility term to the residual test: , and evaluates in the iteration. A small update can signal stagnation; it does not substitute for a small residual.
The preserved teaching loop uses its original conjunction of separate step and gradient conditions, so a single small tested quantity can end the loop. For an implementation intended to certify a candidate, require both and at the same final point, and report a stalled or capped run separately. The analytic cells above evaluate those two quantities after each original experiment, including the singular starts. They supply evidence for interpreting an outcome without hiding the original failure behavior.